
Prompt versioning treats every prompt as an immutable, uniquely identified artefact, retrieved at runtime rather than buried in source code. Do that properly and rollback becomes a configuration change, not an emergency deployment. The real value only appears when each version carries its execution context, model ID, parameters, and template bindings alongside it, so results stay reproducible.
What is prompt versioning and when do teams actually need it?
Prompt versioning is the discipline of storing every meaningful change to a prompt as a distinct, retrievable version rather than overwriting a live string in a config file. Each version gets a unique identifier, a recorded diff from its parent, and a defined path to deployment and rollback. It sounds close to standard source control, and conceptually it is, but the parallel breaks down fast once you look at how prompts actually behave in production.
The practice becomes essential the moment a team ships an LLM feature that customers depend on, iterates on prompts more than a few times a month, or runs the same feature across development, staging, and production with different behavioural expectations. Multi-role teams, where a prompt engineer, a backend developer, and a product manager might all touch the same prompt in a week, need it even sooner.
Plain text diffs in Git tell you what changed. They tell you nothing about whether the change matters:
- A single word swap can shift model behaviour more than a full paragraph rewrite.
- Model drift means an identical prompt can behave differently after a provider updates the underlying model.
- Without eval evidence attached to each version, a diff is just a description of a risk, not a measurement of it.
How should you structure version identifiers and metadata?
Three identifier schemes dominate in practice, and each suits a different context. Sequential versioning (v1, v2, v3) is simple and readable, ideal for internal prompts with a linear history. Semantic versioning, the major.minor.patch convention, works best when prompts are exposed to external integrators who need to know whether a change is breaking. Content-addressable hashing (a SHA of the prompt content) guarantees uniqueness and catches accidental duplication, though it sacrifices human readability. Internal prompts rarely need semver’s ceremony; public-facing prompt APIs usually do.
Whichever scheme you pick, record this metadata with every version:
- Author and timestamp
- A human-readable change message and the parent version ID
- Model ID, temperature, and tokenizer or stop-sequence settings
- A snapshot reference to the eval results that validated the version
Templates need the same discipline. Version the template definition itself, not just the rendered text, and store the parameter schema and default values alongside it, as demonstrated in open template-repository patterns like jonverrier/PromptRepository. Without that, a change to a variable’s default can alter behaviour with no corresponding entry in your history.
Where should versioned prompts live at runtime?
Four storage patterns cover most production setups: a dedicated prompt store or registry, an MCP (Model Context Protocol) server that exposes prompts to agents at call time, a Git-backed repository paired with sync tooling, or a general-purpose config service repurposed for prompts. Open-source registries such as reaatech/prompt-version-control implement tag-based lifecycles, A/B serving, and MCP integration directly, which suits teams that want the runtime layer and the versioning layer in one system.
Runtime resolution comes down to a trade-off between freshness and resilience:
- Per-request fetch with edge caching gives near-instant propagation of new versions but adds a dependency on the prompt store’s availability.
- Build-time snapshotting removes that dependency but means every prompt change requires a redeploy, precisely what versioning is meant to avoid.
- A hybrid pattern, live-fetch with a cached snapshot fallback, gives you fast iteration without a single point of failure.
Each environment, development, staging, production, should pin to an explicit version ID exposed through configuration, never to “latest.” That single rule prevents the most common production incident in prompt-driven systems: an untested change reaching customers because an environment silently tracked the newest version.
How do you promote and roll back a prompt safely?
A defensible promotion workflow has three stages and explicit gates between each one:
- Draft. A new version is authored, tested locally against a sample of real inputs, and attached to its eval snapshot.
- Staging. The version is promoted behind a flag, run against the golden dataset in CI, and reviewed against its similarity verdict and evaluation deltas before anyone signs off.
- Production. The version ships to a small percentage of live traffic first, using weighted routing, with sticky sessions so a single user isn’t switched mid-conversation between two prompt variants.
Canary releases for prompts work the same way they do for application code: start at 5 to 10% of traffic, watch quality and cost metrics for a defined window, then widen the rollout. Set explicit promotion criteria in advance, a minimum eval score, a maximum latency increase, a cost ceiling per request, rather than deciding case by case under pressure. Registries built for this purpose, such as PromptVault, turn rollback into a one-click configuration change instead of a redeploy, which is the entire point of treating prompts as versioned data rather than code.
What should a testing and evaluation gate look like?
A prompt change without an eval gate is a guess dressed up as an update. Build a golden dataset of representative queries drawn from real production traffic, ideally covering edge cases that have caused failures before, and treat it the way you’d treat a unit test suite.
- Run the golden dataset against every new prompt version automatically in CI.
- Block promotion when the version scores below a defined threshold, a gate that open-source prompt registries implement as a hard CI check rather than a suggestion.
- Track quality, cost, and latency together; a version that improves accuracy by 3% but doubles token spend needs a human decision, not an automatic pass.
Pro Tip: Feed every failing eval case straight back into the golden dataset. Most teams write the test suite once and never touch it again, which means it stops reflecting how users actually query the system within a few months.
Why does every LLM call need a version tag?
Attach prompt_id and prompt_version to the metadata of every LLM request and to its trace. Skip this and you lose the ability to answer the one question that matters after something breaks: which version caused it? Tagging every request with its prompt version is described as the single most valuable instrumentation change a team can make for post-hoc regression analysis, and it costs almost nothing to implement.
- Attach the tag at the point of the LLM call, not downstream, so nothing gets lost in async processing.
- Aggregate cost, latency, and quality metrics by version, not just by endpoint, to spot regressions before customers report them.
- When a business metric dips, filter first by version. It narrows a wide investigation to a specific change within minutes.
Build an incident playbook around this: version-tagged alerts trigger, on-call pulls the eval snapshot for that version, and rollback happens before root-cause analysis even finishes.
How do you review a prompt change that actually matters?
Line-level diffs tell a reviewer what text changed. They don’t tell you whether the model will behave differently, which is the question that actually matters. Embeddings-based semantic scoring closes that gap: tools such as promptdiff compute similarity between versions and return a verdict, equivalent, minor, moderate, or major, that maps directly to how much scrutiny the change deserves.
- Wire verdicts into CI so a “major” change automatically requires a full eval run and a human sign-off, while “equivalent” changes can merge with lighter review.
- Show the reviewer the textual diff and the evaluation delta side by side. A prompt can look nearly identical and still fail 15% more golden cases.
- Treat a semantic-impact score as a triage signal, not a substitute for the eval run itself.
How does prompt versioning fit into Git and CI/CD?
Author prompts in Git, where pull requests and code review already work, then sync approved changes to a runtime prompt registry rather than baking them into the application binary. That split is deliberate.
- A CI job runs the golden dataset evals on every prompt pull request and posts a report, similarity verdict, cost delta, quality score, directly on the PR.
- Passing evals publish an automatic staging version; production promotion stays a manual or policy-gated step, never automatic.
- Keep a build-time snapshot as a fallback. Storing prompts purely in Git gives you history and diffs but not deployment state, so a runtime registry is still necessary to know what’s actually live.
This hybrid setup means a copywriting tweak no longer needs a full application redeploy, which is usually the biggest single source of prompt-change friction in growing teams.
How do you stop agentic systems drifting from their guardrails?
Agentic systems introduce a failure mode plain prompt engineering doesn’t: an agent that quietly expands its own behaviour over successive iterations until nobody can say with confidence what it’s actually authorised to do. Guarding against that “vibe drift” requires the same rigour applied to code review, extended to prompts and agent policies.
- Embed policy checks and linting into every promotion gate, not just for the prompt text but for the tools and capabilities an agent version is allowed to invoke.
- Require human-in-the-loop approval before any version reaches production if it changes an agent’s permitted action set.
- Maintain an audit trail that ties every prompt version to its author, its approver, and its eval snapshot, with clear ownership for who gets paged when it fails.
Runtime constraints matter as much as review gates. Rate limiting, capability scoping, and explicit boundaries on what an agent can do should live in the version metadata itself, not in a separate document nobody reads under pressure. A production-ready guardrail framework for agentic development links the prompt version and its decision trace to a named human reviewer, so an incident escalation never stalls on the question of who owns it.
Pro Tip: Treat capability scoping as a version property, not a runtime override. If an agent’s permissions change, that change deserves its own version ID and eval run, the same as a wording edit would.
What’s the fastest way to start versioning prompts?
- Move existing prompts out of hardcoded strings into a managed store, and pick one ID scheme, sequential, semver, or hash, before you write a second version.
- Add the mandatory metadata fields and enable request tagging so every trace carries
prompt_idandprompt_version. - Build a small golden dataset, wire it into CI as an eval gate, and confirm rollback works before you need it under pressure.
Cleverbit’s perspective on embedding versioning into agentic delivery
Prompt versioning without governance is half a solution. Version history gives you traceability; it doesn’t stop a team from promoting an unreviewed version at 2am because the deadline moved. That’s the gap we focus on: review gates that apply whether a prompt was written by an engineer or generated by an agent, trace tagging wired into observability from day one, and CI eval integration that makes promotion evidence-based rather than a judgement call under pressure.
— Cleverbit
How Cleverbit implements prompt versioning and governance in production
Most teams that reach out to us have already built a prompt store, or at least a spreadsheet pretending to be one. What they’re usually missing is the governance layer: review gates that apply consistently, CI eval integration that actually blocks a bad promotion, and an audit trail that survives an incident review. Designs and embeds delivery teams that build that layer in from the start, rather than retrofitting it once an agentic feature is already live and causing problems nobody can trace back to a specific version.
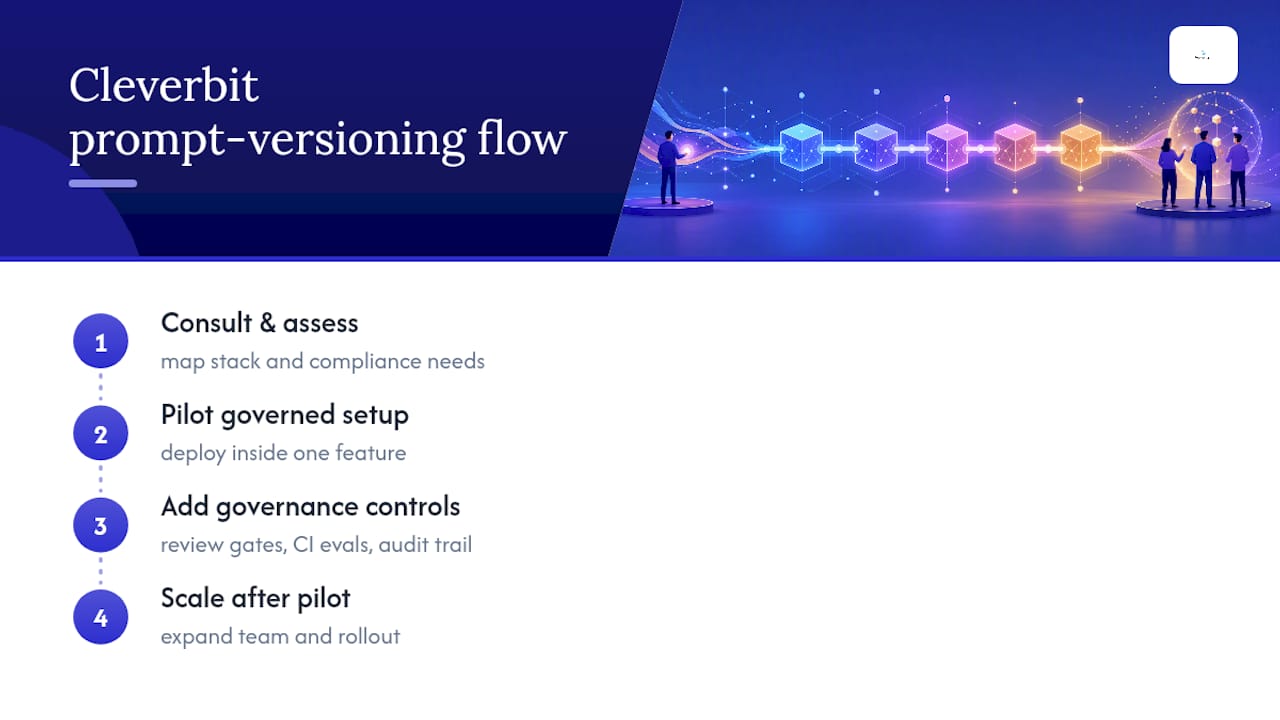
We run this as a consultancy-first engagement: understand your stack and compliance requirements, pilot a governed prompt-versioning setup inside one feature, then scale the team once the pilot proves out. If you’re evaluating how prompt versioning fits into a broader agentic software delivery practice, that’s the right place to start the conversation.
Sources
For teams building this out directly, Semantic Versioning 2.0.0 remains the reference for major.minor.patch conventions where prompts are exposed externally. reaatech/prompt-version-control shows a working registry with eval gates and MCP support, and AmmarAI’s version history feature is a useful reference for how tagged environment releases can be surfaced to non-technical stakeholders.
FAQ
What is prompt versioning?
Prompt versioning is the practice of storing each meaningful change to an AI prompt as a distinct, immutable, uniquely identified artefact, complete with its model settings and template bindings, so it can be retrieved, tested, and rolled back independently of the application code.
What are the best tools for prompt versioning?
Open-source options like reaatech/prompt-version-control and promptdiff cover registry and semantic-diffing needs respectively; teams needing governance built into a managed delivery pipeline typically work with a partner rather than assembling tooling alone.
What does “versioning” mean in this context?
Versioning means assigning a unique, traceable identifier to each distinct state of an artefact, a prompt, a template, a piece of code, so that any state can be retrieved, compared, and restored on demand rather than being overwritten permanently.
What are the three main components of a prompt version?
A complete prompt version needs the prompt text itself, the execution context (model ID, parameters, tokenizer settings), and the evaluation evidence confirming it performs correctly before promotion, alongside its template and variable schema where applicable.
How do you version rendered prompt templates with variables?
Version the template definition separately from the rendered output, and store the parameter schema and default values in the same version record so the exact rendered prompt can be reconstructed at any point later.